Currently Empty: USD$0.00
Home » Python Courses » Data Cleaning & Wrangling with Python
Python 2 · Applied Data Preparation
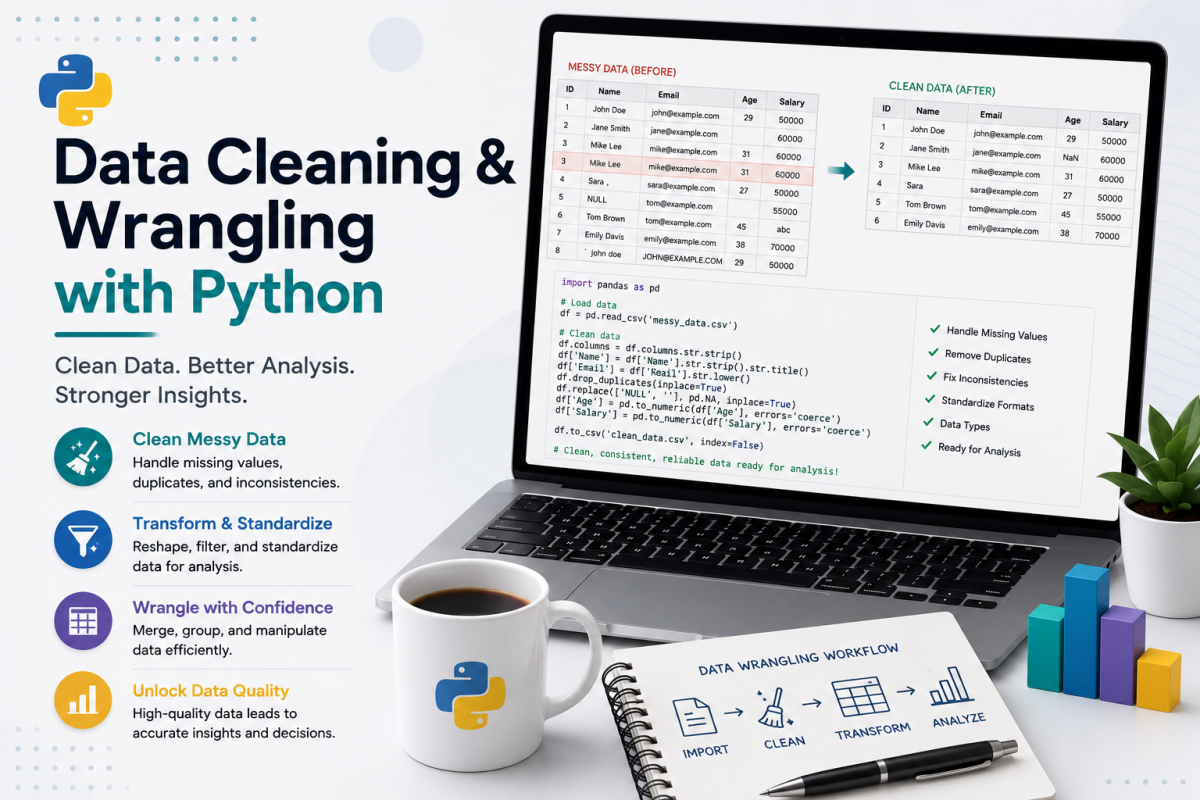
Python 2: Data Cleaning & Wrangling with Python
Turn messy, inconsistent data into reliable analysis-ready datasets using Python and Pandas. Learn the complete cleaning workflow through 8 instructional units, 3 applied projects and 2 capstones.
Original price was: USD$50.00.USD$15.99Current price is: USD$15.99. /month
Self-paced online access · Cancel according to DataSoSi subscription terms.
8 instructional units · 3 individual projects · 2 capstones · Google Colab + interactive project environment · AI Tutor · CiAI certificate
Built for beginners, adult learners and professionals who want practical data-cleaning skills without a computer-science background.
Learn the Cleaning Workflow
Move from first inspection to analysis-ready data using a repeatable sequence.
Complete 3 Projects
Apply each phase of the course in focused project work before the capstones.
Finish 2 Capstones
Complete one Google Colab/Jupyter capstone and one 17-task interactive capstone.
Learn Leakage-Safe Cleaning
Understand which cleaning steps belong before and after the train/test split.
Learn to Turn Dirty Data into Analysis-Ready Data
Real-world datasets rarely arrive clean. Missing values, wrong data types, impossible values, duplicates, inconsistent text and poorly structured tables can quietly undermine analysis and machine-learning models. This course teaches a practical Python workflow for finding those problems, fixing them correctly and verifying the result.
A complete applied workflow
Inspect → diagnose → correct → standardise → split safely → reshape → verify. Learners repeatedly use this workflow so data cleaning becomes a disciplined analytical process rather than a collection of isolated commands.
Core cleaning skills
- Inspect shape, types, summaries and suspicious values
- Measure and treat missing data
- Repair text-formatted numbers and incorrect data types
- Separate invalid values from statistical outliers
- Detect exact duplicates and conflicting keys
- Standardise messy strings, labels and categories
Wrangling and modelling readiness
- Prevent data leakage during preprocessing
- Use train/test splitting at the correct stage
- Learn imputation statistics from training data only
- Combine tables with merge and concat
- Create pivot tables
- Convert wide data to long format with melt
Three Applied Project Phases
The three individual projects mirror the three learning phases in the course, so students practice a coherent part of the workflow before combining everything in the capstones.
Project 1 · Units 1–3
Detect & Diagnose Dirty Data
Audit messy datasets, measure missingness, inspect types and categories, and repair common type and format problems.
Project 2 · Units 4–6
Fix & Standardise Data
Identify invalid values and outliers, remove the correct duplicates, and standardise messy text fields and categories.
Project 3 · Units 7–8
Leakage-Safe Pipeline & Reshape
Split safely, apply training-derived cleaning decisions, merge tables, build pivots and reshape data from wide to long.
Python 2: Data Cleaning & Wrangling — 8 Instructional Units
The curriculum progresses from detecting data-quality problems to correcting them, protecting predictive models from leakage and reshaping clean data for analysis.
Learn the seven types of dirty data and build a reusable first-look inspection routine.
- Missing values, wrong types, duplicates and inconsistent text
- Outliers, structural errors and wrong granularity
.shape,.info(),.describe()and.sample()- Reusable data-quality checklist
Measure missingness precisely, distinguish different types of missing data and choose appropriate treatment strategies.
.isnull().sum()and missing percentages- Hidden missing values and placeholders
- MCAR, MAR and MNAR
- Mean, median, mode, KNN and iterative imputation
- Leakage-safe timing of imputation
Repair numbers stored as text, inconsistent yes/no fields, percentage symbols and categorical data.
- Core Pandas data types
pd.to_numeric()and coercion- Cleaning currency and percentage strings
- Mapping inconsistent booleans
- Using categorical data types
Learn why impossible values and statistical outliers are different problems and how to treat each appropriately.
- Boundary checks with boolean masking
- IQR and Z-score methods
- Replace, cap, drop or retain decisions
.clip()and targeted corrections
Detect exact, key-based, partial and near-duplicate records without deleting legitimate observations.
.duplicated()andkeep=- Business-key conflicts
.drop_duplicates()- Investigating conflicting pairs
Use Pandas string methods and introductory regex to repair inconsistent text fields.
- Whitespace, capitalization and double spaces
- Titles, credentials and structured text
str.replace(),str.split()andstr.extract()- Standardising categories and emails
Learn exactly which cleaning operations are safe before splitting and which must be learned from training data only.
- What data leakage is
- Safe vs unsafe preprocessing operations
train_test_split()- Training-only imputation statistics
- Why the target should not be imputed
Combine tables and reshape analysis-ready data into structures suitable for reporting, visualization and modelling.
pd.merge()and join typespd.concat()pd.pivot_table()pd.melt()- Diagnosing key and column conflicts
3 Individual Projects
Each individual project consolidates a group of units before learners progress to the two larger capstones.
1Individual Project
Dirty Data Audit & Repair
Inspect a messy dataset, diagnose missing values and inconsistent categories, then repair type and formatting errors.
- First-look audit
- Missing-data analysis
- Type and format repair
- Verify corrected outputs
2Individual Project
Data Quality Correction
Work through invalid values, statistical outliers, duplicate records and messy strings using documented decisions.
- Boundary checks
- IQR reasoning
- Duplicate investigation
- String standardisation
3Individual Project
Leakage-Safe Wrangling
Prepare data for predictive modelling without leakage, then merge and reshape tables for downstream analysis.
- Correct split timing
- Training-only statistics
- Merge and pivot
- Wide-to-long transformation
2 Capstones — Two Different Ways to Prove the Skill
The course finishes with two substantial capstones. One requires learners to work independently in Google Colab/Jupyter. The second uses the DataSoSi interactive project environment to reinforce the complete workflow task by task.
Capstone 1 · Google Colab / Jupyter
End-to-End Leakage-Safe Cleaning Pipeline
Work independently with a deliberately messy staff dataset containing 196 records and multiple data-quality problems. Learners decide the order of operations, write the code and verify the final cleaned output.
- Audit the complete dataset before applying fixes
- Correct strings, types, invalid values and duplicates
- Drop missing target rows and perform an 80/20 split
- Learn imputation statistics from training data only
- Build pivot and long-format outputs
- Verify the pipeline with assertions and quality checks
Capstone 2 · Interactive DataSoSi Project
From Dirty Data to Analysis-Ready Data
A 17-task interactive capstone covering all eight instructional units. The dataset is loaded once and students continue through one connected workflow instead of repeatedly starting over.
- Inspect → diagnose → correct → standardise
- Split safely and reuse training statistics
- Merge, pivot and melt
- Run and verify each task
- Use two progressive hints
- Unlock the solution after three failed attempts
- Use the embedded AI Tutor to explain code, output, variables and workplace application
Tools You Will Use
The course uses the core Python tools analysts need for real data-preparation work.
PythonCleaning logic
PandasCore wrangling library
NumPyNumeric operations
Scikit-learnSplit + safe preprocessing
Google ColabIndependent capstone
Continue Your Python Data Science Path
After Data Cleaning & Wrangling, continue in this sequence.
Next 1
Exploratory Data Analysis in Python
Investigate distributions, patterns, relationships and anomalies before modelling.
Explore Exploratory Data Analysis in Python →Next 2
Data Splitting and Preprocessing
Prepare data for machine learning with train/test splitting and modelling-safe preprocessing.
Explore Data Splitting and Preprocessing →Next 3
Building, Evaluating and Interpreting Models
Move from prepared data into model building, performance evaluation and interpretation.
Explore Building, Evaluating and Interpreting Models →Python 2: Data Cleaning & Wrangling Course Details
Format100% self-paced, online
PriceUS$15.99/month
Instructional curriculum8 core units
Individual projects3 applied projects
Capstones2
Capstone environmentsGoogle Colab/Jupyter + interactive DataSoSi workspace
Interactive capstone17 connected tasks
Estimated learning time~24 hours
AI TutorIncluded — course-specific guidance
CertificateCanadian Institute of Artificial Intelligence (CiAI)
Frequently Asked Questions
You will learn how to inspect dirty data, handle missing values, repair data types and formats, identify invalid values and outliers, remove duplicates, standardise text, prevent data leakage, and reshape data with merge, pivot and melt.
The course includes 3 individual applied projects and 2 capstones.
Capstone 1 is an independent Google Colab/Jupyter end-to-end cleaning pipeline on a deliberately messy 196-row staff dataset. Capstone 2 is a 17-task interactive DataSoSi project that walks through the full inspection, cleaning, leakage-safe and reshaping workflow.
Yes. Learners explicitly distinguish safe full-dataset cleaning from operations that must be learned from training data only, including imputation statistics.
Yes. The interactive capstone uses short, focused tasks, embedded data, progressive hints, verification, output explanations and a course-specific AI Tutor so learners can understand each operation rather than memorize a long pipeline.
Continue with Exploratory Data Analysis in Python, then Data Splitting and Preprocessing, and then Building, Evaluating and Interpreting Models.
The certificate of completion is issued by the Canadian Institute of Artificial Intelligence (CiAI).
Meet the Creator of the Course
Learn from an experienced scholar working across machine learning, AI, analytics and applied decision problems.
Dr. Mark Lokanan
Professor · Senior Machine Learning Engineer at Vedia · Senior Machine Learning & AI Scholar
Dr. Mark Lokanan is a Professor at Royal Roads University, a Senior Machine Learning Engineer at Vedia, and a senior machine-learning and AI scholar. His work applies machine learning, deep learning and artificial intelligence to fraud, financial crime, analytics and other complex real-world problems. His teaching focuses on making Python, data science and AI practical and accessible to professionals and adult learners.
Build the Skill Every Data Project Depends On
Learn how to turn messy raw data into trustworthy, model-ready data with a practical Python workflow.
Enroll — US$15.99/monthData Cleaning & Wrangling Assistant
Ask me about the 8 units, 3 projects, 2 capstones, leakage-safe cleaning, price, certificate, or next courses.