Currently Empty: USD$0.00
Home » Python Data Science » Building, Evaluating & Interpreting Models
Python 5 · Applied Machine Learning
Building, Evaluating & Interpreting Machine Learning Models
Move from a model that runs to a model you can defend. Learn the complete machine-learning workflow in Python—from defining the problem and training baselines to tuning, model comparison, final validation, explainability, fairness and expert review.
8 units · 8 individual unit capstones · 2 end-to-end capstones · AI Tutor · CiAI certificate
Original price was: USD$50.00.USD$15.99Current price is: USD$15.99. /month
Self-paced online learning · Cancel according to DataSoSi subscription terms.
Designed to teach the reasoning behind model decisions—not rote memorization of code.
8 Unit Capstones
Every unit ends with a focused capstone so learners apply the technique before moving forward.
Notebook Capstone
Complete a full HR turnover modeling project in Google Colab or Anaconda.
Interactive Capstone
Apply the complete workflow again in DataSoSi's guided project environment with embedded support.
Explainable ML
Go beyond accuracy to interpret model behavior, assess fairness and communicate decisions.
Learn the Complete Machine Learning Model Workflow
A useful model is not simply one that produces a high score. Professional machine learning requires a defensible sequence of decisions: define the problem correctly, train comparable models, validate them reliably, choose metrics that fit the business cost of errors, interpret what the model learned, assess fairness, and obtain expert validation before deployment.
What the course is really teaching
You do not need to memorize every scikit-learn function. The course focuses on what technique fits the problem, why the result is trustworthy, and how to explain the result to a non-technical stakeholder.
Stage 1
Define
Identify the target, problem type, class balance and baseline.
Stage 2
Train & Validate
Use fit/predict correctly and diagnose train-vs-validation gaps.
Stage 3
Tune
Search hyperparameters with Grid, Randomized and Bayesian methods.
Stage 4
Compare
Evaluate candidate models using a fair and repeatable pattern.
Stage 5
Measure
Use Accuracy, Precision, Recall, F1 and ROC AUC appropriately.
Stage 6
Visualize
Read confusion matrices, ROC curves and threshold trade-offs.
Stage 7
Select
Use cross-validation and the sealed test set for final selection.
Stage 8
Explain & Validate
Interpret features, assess fairness and confirm findings with experts.
Course Curriculum — 8 Units
The same HR employee-turnover problem is used across the units so learners see model development as one connected workflow rather than eight disconnected techniques.
Identify classification versus regression problems, define the target, inspect class balance, create the first train/test split and train an interpretable baseline model.
- Problem framing
- Classification vs regression
- Target definition
- Baseline selection
- Logistic Regression baseline
- Initial multi-model comparison
Apply the fit/predict pattern, compare training and validation performance, recognize overfitting and underfitting, and use stratified cross-validation for a more reliable estimate.
- fit() and predict()
- Training vs test performance
- Overfitting and underfitting
- StratifiedKFold
- Cross-validation scores
- Generalization
Understand the difference between model parameters and hyperparameters, then tune models using GridSearchCV, RandomizedSearchCV and Bayesian optimization with Optuna.
- Model parameters vs hyperparameters
- GridSearchCV
- RandomizedSearchCV
- Bayesian optimization
- Optuna
- CV-based tuning
Train Logistic Regression, Random Forest and XGBoost using the same data and a consistent comparison pattern, then create a performance summary table.
- Candidate model families
- Logistic Regression
- Random Forest
- XGBoost
- Consistent model loops
- Fair model comparison
Generate class predictions and probability scores, then evaluate models with metrics that reflect the real business cost of mistakes.
- Class predictions
- Probability scores
- Accuracy
- Precision and Recall
- F1 Score
- ROC AUC
- Confusion matrix
Turn metrics into visual evidence using confusion-matrix heatmaps, ROC curves, actual-versus-predicted comparisons and Precision-Recall threshold analysis.
- Confusion-matrix heatmaps
- ROC curves
- AUC comparison
- Actual vs predicted charts
- Precision-Recall thresholds
- Choosing appropriate visuals
Compare models across folds, collect multiple metrics, tune the leading model and evaluate the final selected model on the sealed test set only once.
- CV mean and standard deviation
- cross_validate()
- Multi-metric validation
- GridSearchCV
- Final model selection
- Sealed test-set evaluation
Interpret Logistic Regression coefficients and Random Forest feature importances, examine subgroup performance with fairlearn, distinguish association from causation, and understand why expert validation is the final step before deployment.
- Logistic Regression coefficients
- Feature importance
- Model explainability
- Fairness analysis with fairlearn
- Subgroup performance
- Association vs causation
- Expert validation
8 Individual Capstones — One for Every Unit
Each unit ends with an applied capstone so learners practise the exact decision they have just learned before adding the next stage of the workflow.
Capstone 1 · Unit 1
Problem Definition & Baseline
Frame the prediction problem, define the target, inspect class balance, create an initial split and establish a baseline model.
Capstone 2 · Unit 2
Training & Cross-Validation
Train candidate models, compare training and validation performance, and use stratified CV to evaluate generalization.
Capstone 3 · Unit 3
Hyperparameter Tuning
Tune model settings with structured search methods and compare whether tuning improves cross-validated performance.
Capstone 4 · Unit 4
Multi-Model Comparison
Train Logistic Regression, Random Forest and XGBoost under the same conditions and build a fair comparison table.
Capstone 5 · Unit 5
Prediction & Metrics
Generate labels and probabilities, calculate classification metrics, inspect the confusion matrix and interpret error costs.
Capstone 6 · Unit 6
Performance Visualization
Create visual diagnostics that reveal behavior not visible in a metrics table, including ROC and threshold trade-offs.
Capstone 7 · Unit 7
Final Model Selection
Use cross-validation, tuning and the sealed test set to select and justify a final model without contaminating evaluation.
Capstone 8 · Unit 8
Interpretation, Fairness & Expert Review
Explain feature effects, examine subgroup performance, assess fairness concerns and prepare the model for expert validation.
2 End-to-End Capstones
After the eight unit capstones, learners complete the full modeling workflow twice in different environments: once independently in a notebook and once through DataSoSi's guided interactive project experience.
Capstone 1 · Google Colab or Anaconda
HR Employee Turnover — Full Notebook Project
Work independently with a separate HR employee-turnover dataset and complete the complete modeling workflow as a professional notebook assessment.
200employee records
28.5%turnover rate
8workflow sections
- Inspect and explain the dataset before modeling.
- Explore relationships and business-relevant patterns.
- Create leakage-safe training, validation and test sets.
- Train Logistic Regression, Random Forest and XGBoost.
- Compare Accuracy, Precision, Recall, F1 and ROC AUC.
- Visualize performance and threshold trade-offs.
- Use cross-validation and tuning for final model selection.
- Interpret the selected model, assess fairness and write professional reflections.
Capstone 2 · DataSoSi Interactive Project
Final Interactive Machine Learning Capstone
Repeat the end-to-end workflow in a guided project environment designed to help learners reason through each decision while still writing and running the Python themselves.
8workflow stages
2progressive hints
AIcourse tutor
- Task-by-task Python workspace rather than a passive tutorial.
- Run and verify code before moving forward.
- Progressive hints when learners get stuck.
- Explain Code, Explain Output and Explain Solution support.
- Embedded AI Tutor grounded in the course workflow.
- Focus on why a model decision is appropriate—not only whether the code executes.
Tools and Techniques You Will Use
Pythonmodel-development language
pandasdata handling
scikit-learntraining, CV and metrics
XGBoostboosted tree model
OptunaBayesian tuning
fairlearnfairness analysis
Matplotlibmodel visualization
Seaborndiagnostic charts
Google Colabnotebook capstone
Anacondalocal notebook option
ROC / PRthreshold analysis
Cross-Validationreliable model selection
Who This Course Is For
The course is designed for learners who already understand Python data analysis and preprocessing and are ready to build complete machine-learning models without jumping straight from code to an accuracy score.
Data & Business Analysts
Move from descriptive analysis into predictive modeling while learning how to justify model choices to decision-makers.
Non-Computer-Science Professionals
Learn the logic of machine learning through a structured workflow rather than a theory-heavy computer-science approach.
Aspiring Data Scientists
Build a portfolio-ready understanding of training, tuning, evaluation, explainability and fairness before moving into more advanced ML work.
Course Details
Format100% self-paced, online
Instructional units8
Individual capstones8 — one per unit
End-to-end capstones2
Total applied assessments10
Notebook environmentGoogle Colab or Anaconda
Core modelsLogistic Regression, Random Forest, XGBoost
Core librariespandas, scikit-learn, xgboost, fairlearn, matplotlib, seaborn
AI TutorIncluded — course-specific guidance
CertificateIssued by the Canadian Institute of Artificial Intelligence (CiAI)
PriceUS$15.99/month
Frequently Asked Questions
It teaches the complete workflow for building, evaluating and interpreting machine-learning models: problem definition, baselines, training, cross-validation, hyperparameter tuning, model comparison, evaluation metrics, visualization, final model selection, explainability, fairness and expert validation.
There are 8 individual capstones—one for each unit—plus 2 end-to-end capstones, giving learners 10 applied assessments across the course.
The notebook capstone uses a 200-row HR employee-turnover dataset with a 28.5% turnover rate. Learners apply the full eight-stage modeling workflow and document both their technical results and business interpretation.
The second capstone is completed in the DataSoSi interactive project environment. Learners work through the modeling workflow task by task with code execution, verification, hints, code and output explanations, and an embedded course-specific AI Tutor.
The course covers Accuracy, Precision, Recall, F1 Score, ROC AUC and confusion matrices, with emphasis on choosing metrics based on the business cost of false positives and false negatives rather than relying on Accuracy alone.
Yes. Learners interpret Logistic Regression coefficients and Random Forest feature importances, assess subgroup model performance with fairlearn, distinguish statistical association from causation, and understand why domain-expert validation is required before a model influences real decisions.
Data Splitting & Preprocessing for Machine Learning is the recommended preceding course because it establishes leakage-safe data preparation before model development.
The course is created by Dr. Mark Lokanan, Professor at Royal Roads University, Senior Machine Learning Engineer at Vedia, and a senior machine learning and AI scholar whose work connects machine learning, data science, artificial intelligence, analytics and applied decision problems.
Meet the Creator of the Course
Learn from a senior machine-learning practitioner and scholar working across AI, data science and applied analytics.
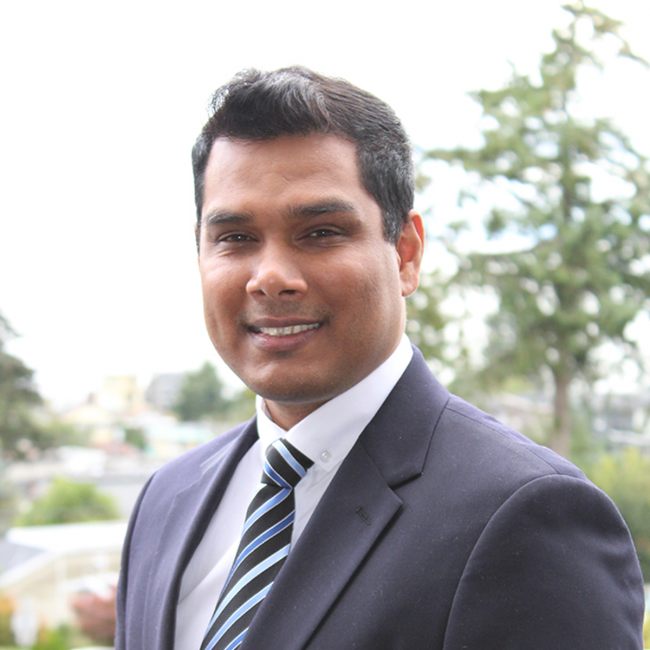
Dr. Mark Lokanan
Professor · Senior Machine Learning Engineer at Vedia · Senior Machine Learning & AI Scholar
Dr. Mark Lokanan is a Professor at Royal Roads University and Senior Machine Learning Engineer at Vedia. His work spans machine learning, artificial intelligence, data science, analytics and financial-crime research, with a strong focus on applying advanced analytical methods to real-world decision problems. His teaching emphasizes practical, interpretable and responsible AI for professionals and adult learners.
Machine Learning Course Assistant
Ask me about the 8 units, 8 individual capstones, 2 end-to-end capstones, metrics, model comparison, explainability, fairness, or course preparation.